omics.co.in logo omics.co.in
🧬 TRACK 18 • 10 MODULAR CHAPTERS BEGINNER-FRIENDLY • PRODUCTION READY FASTQ • HISAT2 • featureCounts • DESeq2 • STRING
Next-Generation Sequencing • End-to-End Transcriptomics Workflow

Practical NGS & RNA-Seq Data Analysis: From Raw FASTQ to Differential Expression & Functional Networks

The Complete Hands-On Training: FASTQ Quality Assessment, fastp Trimming, HISAT2 Spliced Alignment, featureCounts Matrix Building, DESeq2 Statistical Modeling, Publication Figures & STRING PPI Networks.

Designed for students, biomedical researchers, and biotech professionals seeking production-grade computational skills in transcriptomics. Master the complete experimental and analytical workflow: from sequencing chemistry biophysics and public SRA data retrieval to multi-threaded read trimming, splice-aware alignment against eukaryotic reference genomes, negative binomial dispersion shrinkage in R, and biological network discovery with STRING and clusterProfiler.

⚡ Production Conda / Mamba Environment Bioconda + Conda-Forge
# Install the complete RNA-Seq production toolchain in one step
mamba create -n omics_rnaseq -c bioconda -c conda-forge \
  sra-tools pigz fastqc multiqc fastp hisat2 samtools qualimap subread \
  r-base bioconductor-deseq2 bioconductor-enhancedvolcano r-pheatmap \
  bioconductor-clusterprofiler bioconductor-org.hs.eg.db -y

conda activate omics_rnaseq
Start Module 1 → 📊 Complete 10-Step Workflow ↓ Bulk RNA-Seq Pipeline Blueprint →
End-to-End Analytical Pipeline

The Complete 10-Step RNA-Seq Workflow

Every stage from experimental wet-lab design through statistical differential testing and network topology:

STEP 01
NGS Chemistry
Illumina SBS, Cluster Gen
STEP 02
Library Prep
Poly(A) vs Ribo-Zero, Replicates
STEP 03
Data Ingestion
SRA Toolkit, fasterq-dump
STEP 04
Raw Read QC
FastQC, MultiQC Dashboard
STEP 05
Read Trimming
fastp, Poly-G Clipping
STEP 06
Spliced Mapping
HISAT2 HGFM Index
STEP 07
Alignment QA
Samtools, Qualimap RNA-seq
STEP 08
Quantification
featureCounts Count Matrix
STEP 09
DESeq2 Analysis
Negative Binomial, apeglm
STEP 10
Plots & STRING
Volcano, PCA, PPI Networks
Curriculum Syllabus

10 Hands-On Modular Chapters

Click any module to launch the complete interactive chapter with code, commands, and datasets →
Module 01 Module 01 • Foundations

Module 1: Introduction to Next-Generation Sequencing & RNA-Seq Fundamentals

Core concepts of high-throughput transcriptomics: Illumina Sequencing-by-Synthesis (SBS) chemistry, flowcell cluster generation, paired-end vs. single-end reads, and dynamic range of transcriptome quantification.

Read Module →
Module 02 Module 02 • Experimental Design

Module 2: Experimental Design, Library Preparation Strategies & Sequencing Depth

Designing rigorous RNA-seq experiments: biological vs. technical replicates, power analysis, Poly(A) mRNA selection vs. Ribo-Zero ribosomal RNA depletion, strandedness (dUTP second-strand), and target coverage.

Read Module →
Module 03 Module 03 • Data Management

Module 3: Data Management, Project Architecture & Public Repository Retrieval (SRA / GEO)

Structuring reproducible bioinformatics directories, MD5 checksum integrity validation, downloading public benchmark datasets with fasterq-dump (SRA-Toolkit), and batch sample sheet metadata generation.

Read Module →
Module 04 Module 04 • Quality Control

Module 4: Quality Control of Raw Reads: Phred Scores, FastQC & MultiQC Diagnostics

Deconstructing the 4-line FASTQ structure, mathematical Phred quality scores Q = -10 log10(P), interpreting FastQC diagnostic plots (per-base quality, GC bias, adapter contamination), and aggregating reports with MultiQC.

Read Module →
Module 05 Module 05 • Preprocessing

Module 5: Read Trimming, Adapter Clipping & Quality Filtering with fastp & Trimmomatic

Automated adapter detection, sliding-window Phred quality filtering, poly-G tail clipping on two-color chemistry (NovaSeq/NextSeq), low-complexity read filtering, and post-filtering verification.

Read Module →
Module 06 Module 06 • Spliced Alignment

Module 6: Spliced Read Alignment to Reference Genome with HISAT2

Why traditional DNA aligners fail on eukaryotic mRNA: Hierarchical Graph FM-index (HGFM) architecture, indexing genomes with splice sites and exons, HISAT2 alignment execution, and generating SAM streams.

Read Module →
Module 07 Module 07 • Alignment QA

Module 7: Alignment Post-Processing & Quality Assessment with Samtools & Qualimap

Converting SAM to coordinate-sorted BAM with samtools, indexing, flagstat alignment rate validation, and comprehensive Qualimap RNA-seq diagnostics: 5'-to-3' gene body coverage bias, genomic origin, and saturation curves.

Read Module →
Module 08 Module 08 • Quantification

Module 8: Gene Expression Quantification with featureCounts (Subread Suite)

Building the gene-level raw count matrix: GTF/GFF3 exon feature parsing, resolving multi-overlapping reads, stranded count flags (-s 1 / -s 2), paired-end fragment counting (-p -B), and formatting the raw counts matrix.

Read Module →
Module 09 Module 09 • DESeq2 Analysis

Module 9: Differential Gene Expression Analysis with DESeq2 in R

Mathematical foundations of count data modeling: Negative Binomial distribution, size factor median-of-ratios normalization, empirical Bayes dispersion shrinkage, Wald testing, and log2 fold-change shrinkage (apeglm).

Read Module →
Module 10 Module 10 • Visualization & Networks

Module 10: Publication-Grade Visualizations & STRING Functional Network Enrichment

Generating publication-ready figures in R: Volcano plots (EnhancedVolcano), Principal Component Analysis (PCA), hierarchical clustering heatmaps (pheatmap), MA plots, and functional PPI network mining with STRING and clusterProfiler.

Read Module →
Official Course Overview

Interactive Training in NGS RNA-Seq Data Analysis

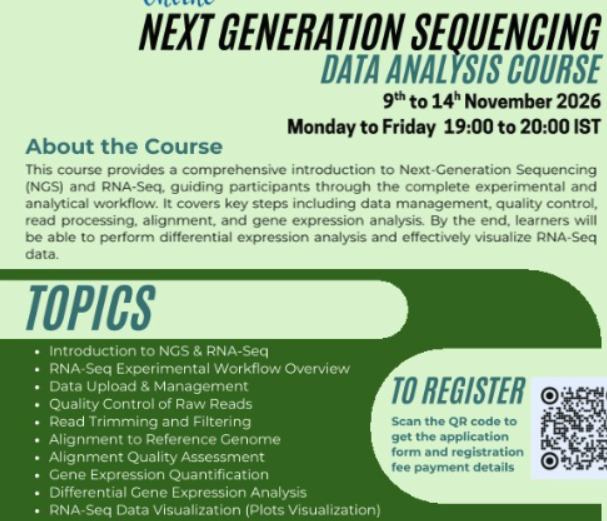
This comprehensive curriculum guides participants through the complete experimental and analytical RNA-seq workflow. From data upload and quality control of raw reads through spliced alignment, gene quantification, and differential expression, learners will be able to perform robust statistical testing and generate publication-grade figures.

What You Will Master:

  • Complete terminal Linux commands (FastQC, fastp, HISAT2, samtools, featureCounts)
  • Statistical count data normalization with DESeq2 (Negative Binomial GLM)
  • Interactive Volcano, PCA, Heatmap and MA plots with ggplot2 and pheatmap
  • Functional Protein-Protein Interaction (PPI) networks with STRING & GO biological processes with clusterProfiler
Start Free Self-Paced Training →
NGS RNA-Seq Data Analysis Course Overview Flyer